
AI usage control for Windows devices
Control what
your organisation
sends to AI
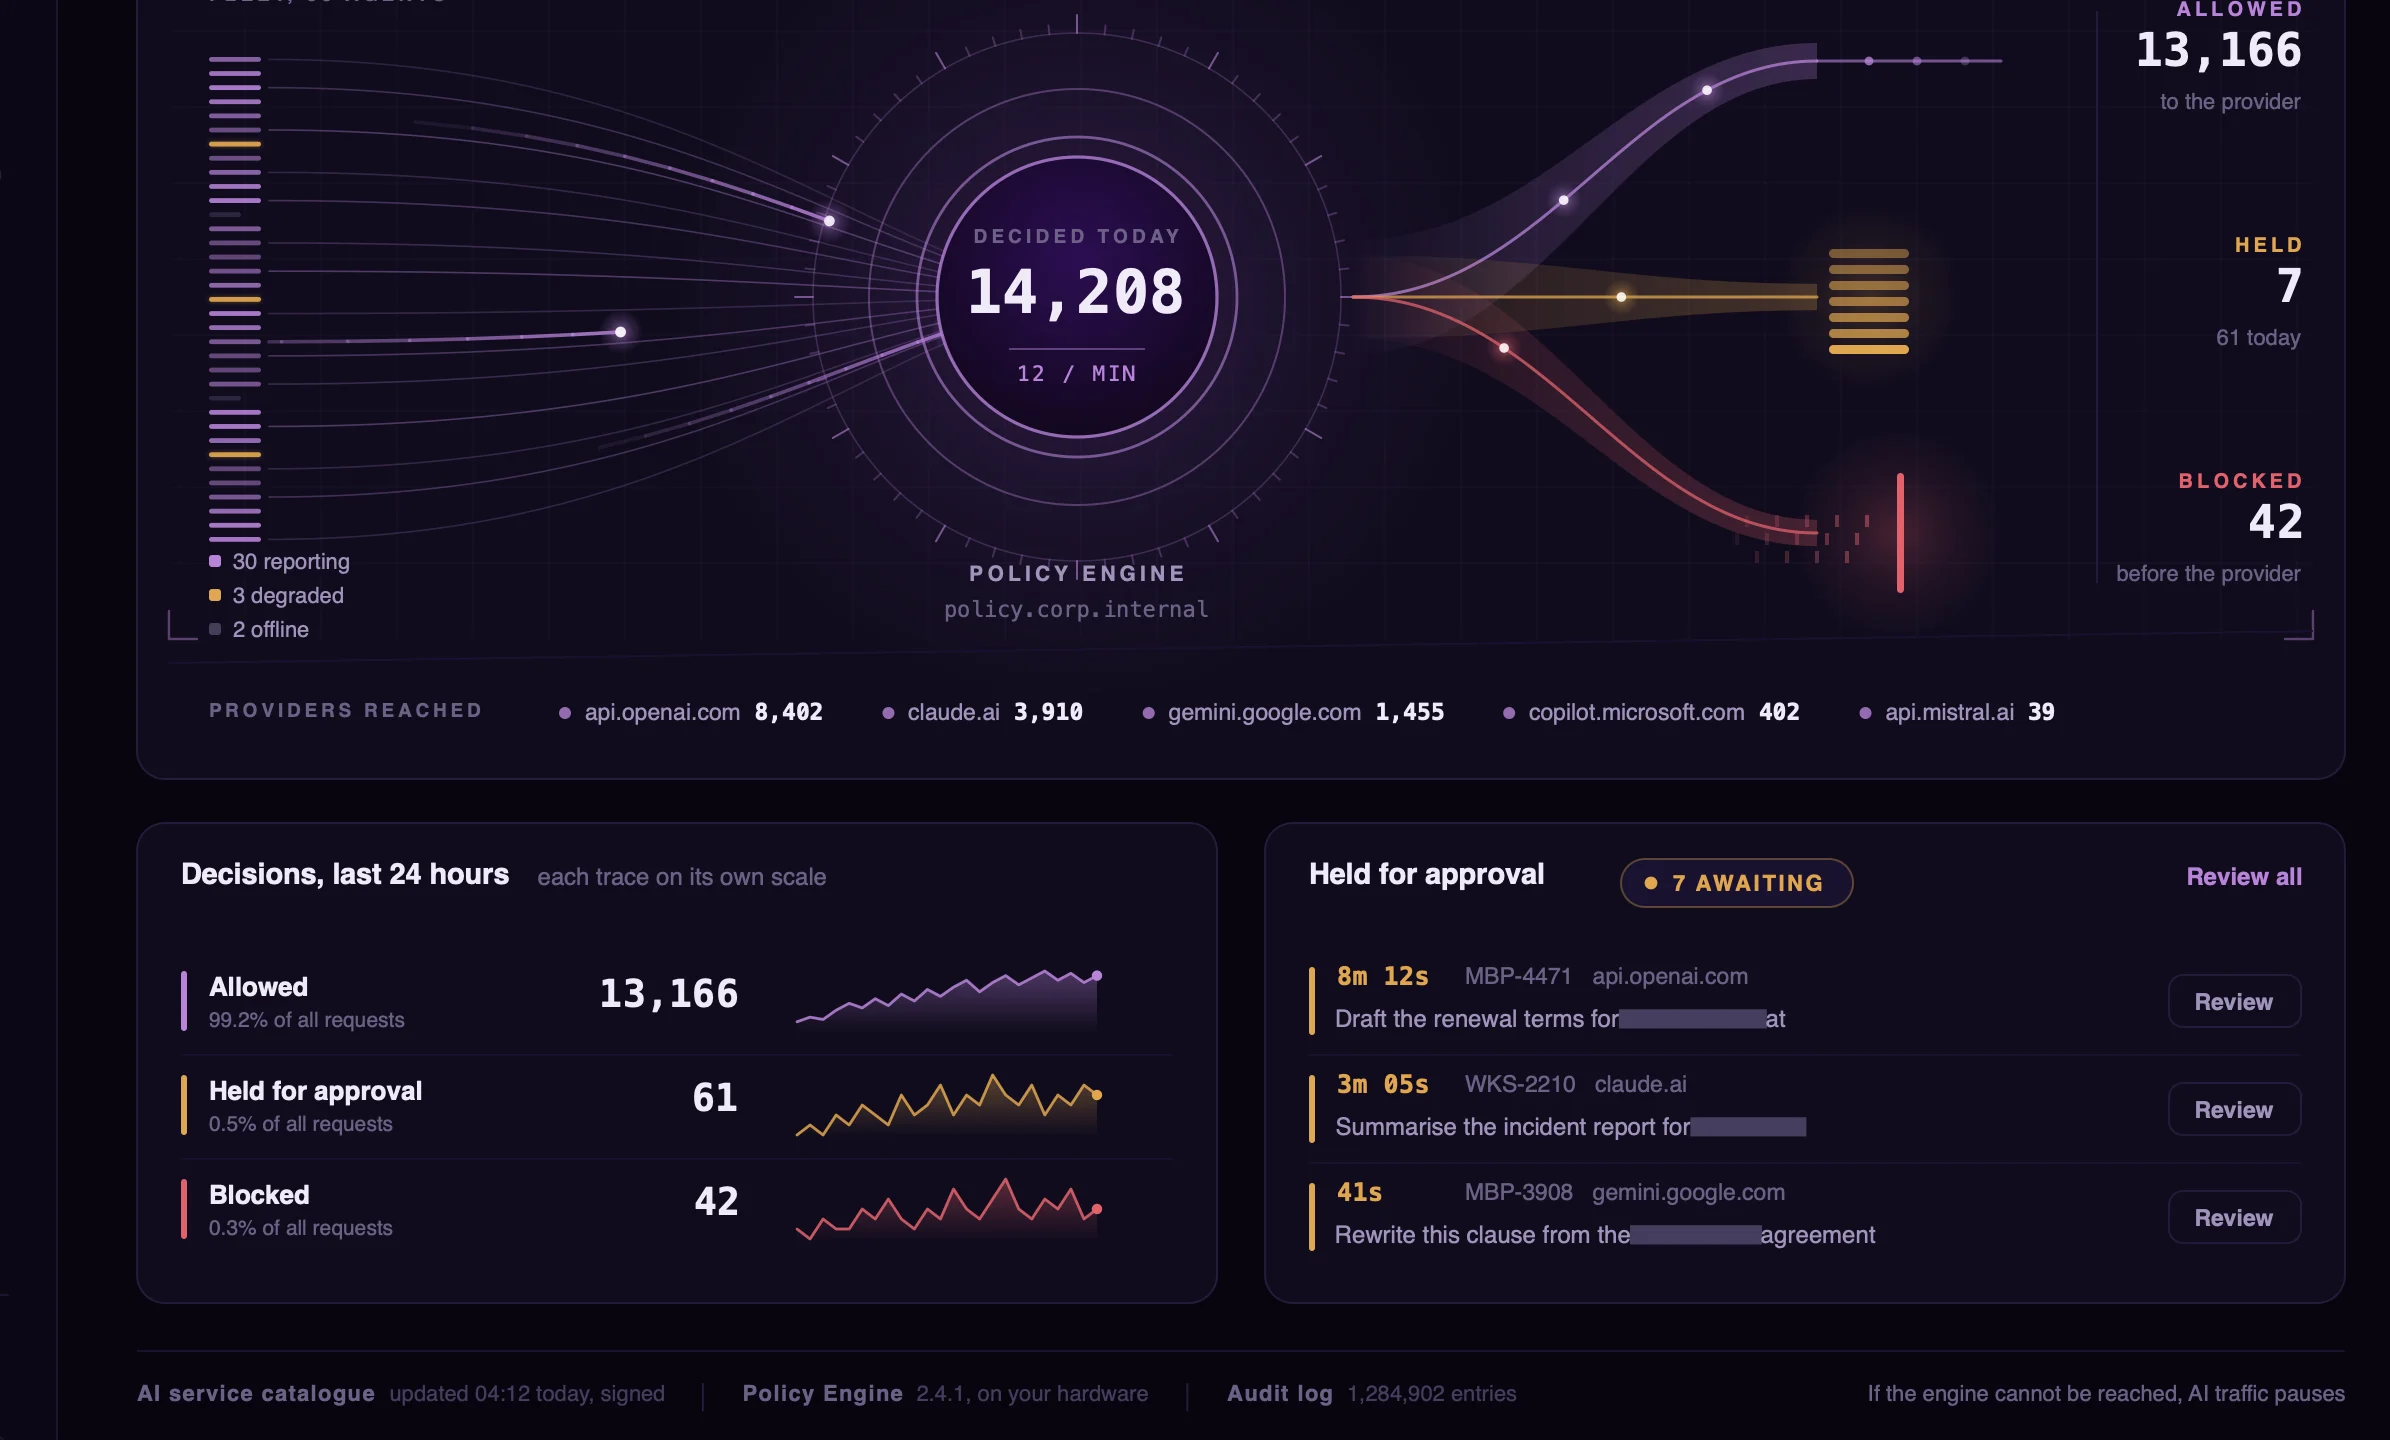
LLMGuard by HACS checks every request your devices send to AI services and blocks the ones containing intellectual property or confidential information before they reach the provider.
- Runs on
- Your own servers
- Devices
- Windows at launch
- Deployed through
- Your existing Intune
- Inspection
- Before the request leaves
01 / WHY THIS EXISTS
Nobody did anything wrong.
Someone on your team has a contract open and a deadline. They paste a clause into ChatGPT and ask it to check the indemnity wording. It takes four seconds, the answer is good, and the work gets done.
The client name, the contract value and the account numbers are now held by an AI company.
No policy was broken, no attacker was involved, and nothing in your security stack recorded it. There is no log to find, because nothing was watching this route.
Can you check the indemnity wording in this clause?
12.3 Indemnity. client name1 shall indemnify the Supplier against all losses arising from the Services, up to a total of contract value2. Payments under this clause are made to account account number3.
Every other route out is covered.
You have spent years closing these. The controls work, they are audited, and they are why data does not walk out through email or a file share.
- EmailSecure gateway
- File serversData loss prevention
- SharePointSensitivity labels
- Removable mediaDevice control
- An AI chat boxNo controlAI provider
You decide what confidential means.
LLMGuard reads each request for meaning against rules like this one. It is not matching a keyword list, so a client name it has never seen before is still a client name.
Client names, contract values and account numbers are confidential.
LLMGuard works alongside your endpoint security and DLP tools. It covers the one route they were not built for.
02 / WHERE IT RUNS
The engine is yours,
and it sits on your hardware.
Your rule has to be read against the actual content of a request, so that content goes to the Policy Engine. The Policy Engine is installed in your environment, on your own hardware, and it is the only place a decision is made.
If a device cannot reach the engine, you decide what happens.
Devices reach the Policy Engine on your network or over your VPN. When one cannot, AI traffic either pauses or continues, and you choose which in advance.
- What gets opened
- Only traffic to AI services. Banking, health and personal traffic is left sealed.
- On the record
- Every decision is logged with the device, the service and a fingerprint of what was sent.

03 / EVERY APP. EVERY AI.
Use every AI tool.
Your rules decide what it receives.
From browser assistants to desktop apps, command-line agents and API calls, LLMGuard reads the content itself, not just the destination. Your own policy decides what reaches the provider.
- Browsers
- IDE coding assistants
- Desktop AI apps
- Command-line agents
- Scripts
- SDK and API calls
A browser plug-in would see only the first of these.
Can you check the indemnity wording in this clause?
12.3 Indemnity. client name1 shall indemnify the Supplier against all losses arising from the Services, up to a total of contract value2. Payments under this clause are made to account account number3.
This request was not sent. It contains information your organisation does not allow to leave for an AI service. IT has been notified.
chat.openai.com- More than 50 AI services
- Recognised by the agent. New ones arrive by signed update, with nothing reinstalled on devices.
- The service, not the cloud
- It identifies the AI service itself, so business applications on the same cloud are not caught.
- One policy
- Set centrally, it applies to every device and every AI provider.
- No application changes
- No SDK, no proxy settings, no developer work.
04 / DEPLOYMENT
We install it on site,
with your IT team.
Our deployment team installs the Policy Engine in your environment, trains it there, and handles setup and integration until LLMGuard is live. Your IT team pushes the agent through the device management it already runs. How long setup takes depends on your environment, so we agree the plan with you before anything is installed.
Agree
Before anything is installed
Your team
- Windows devices, managed through Intune or similar
- A server for the Policy Engine, to our stated requirements
- Devices that reach it on your network or VPN
- An IT contact for installation and coordination
HACS
- Scope, costs and terms, agreed in writing before we start
- The rollout plan and your starting policy, set with your IT contact
Install
On site, in your environment
Your team
- Push the agent to a device group through Intune
- Devices enrol themselves
HACS
- Installs the Policy Engine on your server and handles setup and integration
- Trains it there, on your own material
- Takes its training setup and temporary equipment away. The system stays with you.
LLMGuard is live
Evaluate
For a period agreed with you
Your team
- Your administrators run the Policy Engine: held requests, policy, exceptions and business context
HACS
- Works through the evaluation with you
- Collects your feedback on its decisions
Run
From then on
Your team
- Send feedback on decisions. It improves the models in the next training iteration.
HACS
- Runs each training iteration on site
- Review visits planned every six months, with support between them
- Never connects into your network
Check the rollout from the Policy Engine.
The Intune screen compares every Windows device Intune manages with the devices the engine has actually heard from. A device the push missed is listed, with the reason.

05 / THE COMPANY
HACS is the company
behind LLMGuard.
HACS was founded to help organisations adopt AI without exposing confidential information. We’re building protection that runs within the customer’s own environment, with the needs of small and medium businesses in mind.
The product came first.
LLMGuard began as an answer to one problem: letting people use AI at work without confidential information reaching AI companies. We felt that problem was poorly served, especially for smaller organisations, so HACS was founded to take LLMGuard to market.
The team that builds LLMGuard is the team that installs it in your environment, trains it there and supports it afterwards.
The founders
- Harshini VarmaDirector and CEO
- RamrajuFounder
- Registered as
- HACSCO AI Private Limited
- Based in
- Hyderabad, India
- Early-access pilots
- India, the UAE and Qatar
- Contact
- connect@hacsglobal.co
Bring protection
inside.
Apply for an on-premises pilot supported by the HACS team.